profile
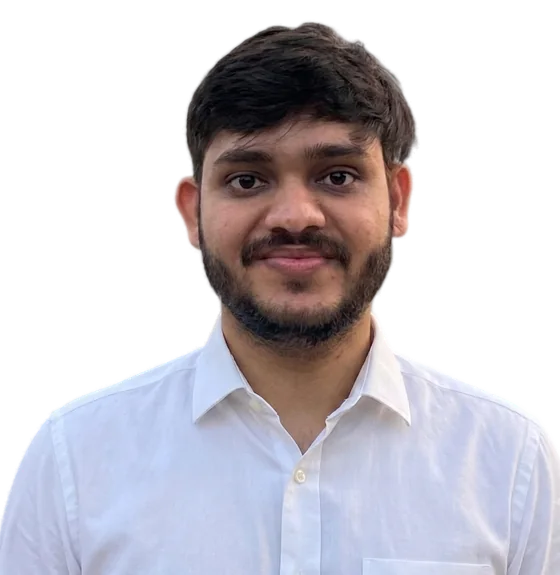
Hello, I'm Jitendra.
Engineer by habit, architect by role.
I design AI platforms end to end: agents, model serving, GPU scheduling, and the cloud bill that comes after.
Cloud/DevOps intern in January 2024, Technical Architect in Centific's Digital Architecture Centre of Excellence by April 2025. Today I lead AI and AIOps R&D for the AI Data Foundry.
- now
- AI Engineer (Technical Architect), Centific
- based in
- Hyderabad, India
- studied
- B.Tech IT, IIIT Allahabad · 2024
- recognised
- Star Performer Award · mentored a hackathon-winning team
what I do, usually
My infinite loop.
Four steps, on repeat. Tap a step to pause the loop there.
01 / 04
Develop
experience
The climb.
Intern to Technical Architect in about fifteen months.
APR 2025 — PRESENT
AI Engineer (Technical Architect)
Centific Global Technologies · Digital Architecture Centre of Excellence
- Lead AI/AIOps R&D for the AI Data Foundry; onboarded 150+ users in the USA and India.
- Built a resume screening and assessment agent: 6,000+ applicants, 2,000+ assessments, top 200 shortlisted.
- Prototyped a humanoid meeting agent that joins live calls, converses with turn-taking and files live web reports.
- On-demand GPU offloading across Azure, RunPod, Denvr and on-prem: 30–50% cheaper inference/training, peak spend $90K → $30K.
- CLI runtime installer took on-prem customer deployments from 1 week to 1–2 days.
JUL 2024 — APR 2025
Associate Software Engineer (AI/MLOps)
Centific · Core AIDF Engineering Team
- DevSecOps-integrated Manifest Engine for secure AI deployments, saving ~6 hours per release.
- Scalable AI Orchestration Engine: multi-step pipelines and dynamic payload exchange between AI services.
- Automated Hugging Face deployments on AKS, Databricks, RunPod and on-prem; 70% faster inference with vLLM.
- In-house Kubernetes GPU resource manager for on-prem GPU scheduling and control.
- Owned an AWS security incident heading to $150–200K/month: escalated, rebuilt a sanitised account, hardened controls.
JAN 2024 — JUL 2024
Cloud / DevOps Intern
Centific
- Terraform for Azure VNets, App Services and Storage: 70% less manual effort, 60% faster setup.
- Dynamic CI/CD on the Azure DevOps REST API, release cycles halved.
- CloudOps/FinOps/SecOps dashboard over 100+ resources; monthly spend down 20–30%.
projects
Things I've built.
Tap a card to flip it and see the stack and the numbers.
skills
The skill galaxy.
Each orbit is one area. Pick an area to light it up, or hover a planet.
conversation
Ask my AI twin.
It answers from my resume, so you don't have to read it.
Questions recruiters usually ask, answered instantly.
Ask about projects, GPU cost savings, the stack, education or how to reach me. Answers come from the facts on this page.
Jitendra's AI twin● online
contact
Let's build
something brilliant.
© 2026 Jitendra Yadav · Hyderabad, Indiaparticles, canvas and a little physics